Put Your Data to Work with High-Precision AI Infrastructure
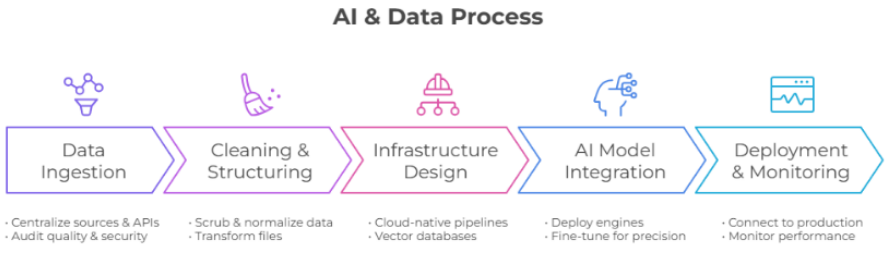
We transform fragmented, messy data into clean, secure data engines—giving your AI tools the reliable foundation they need to deliver accurate insights and predictions.
What to Expect from Our Data Engineering
An AI model is only as smart as the data feeding it. We ensure your business data is structured, secure, and ready to power intelligent tools that your team can actually trust.
What We Build & Optimize Together:
- Data Centralization & Unification: Breaking down silos by bringing spreadsheets, databases, and APIs into a single source of truth.
- Data Cleaning & Structuring: Scrubbing, validating, and organizing files and logs for accurate AI inputs
- Scalable Infrastructure: Architecting secure, cloud-native pipelines that automatically sync as your business grows.
- Context-Aware Retrieval: Connecting internal knowledge bases using advanced search (like RAG) for precise, hallucination-free answers.
- Predictive Analytics: Turning historical records into predictive models and automated enrichment pipelines.
What You Walk Away With
You get more than just database updates—you receive production-ready data engines designed to keep your AI solutions relevant and actionable over the long haul.
- 🗄️ Unified Data Pipeline: Automated workflows that ingest, clean, and sync company data continuously.
- 🔍 Precision Retrieval Engine: Queryable AI knowledge base retrieving internal documentation instantly.
- 📊 Predictive Models: Custom data engines built for forecasting and automated insights.
- 🔒 Secure Governance: Enterprise-grade security and access controls to protect confidential data.
Is AI & Data Engineering Right for You?
Ideal For:
- Scattered Data Teams: Companies with data stored across multiple disconnected systems and spreadsheets.
- Accurate AI Seekers: Teams wanting internal AI that answers questions without making things up.
- Growing Startups & SMEs: Organizations needing a strong data foundation before rolling out automation.
FAQOpen questions from our customers
Why do we need data engineering before building AI tools?
AI models rely heavily on the quality of data provided. If your underlying data is messy, incomplete, or siloed, the AI will produce inaccurate or unreliable results. Data engineering ensures the information feeding your AI is clean, structured, and trustworthy.
What if our data is stored in legacy databases or scattered spreadsheets?
That is where we start. We specialize in connecting legacy systems, extracting messy records, and building modern pipelines that clean and format your data without disrupting your day-to-day operations.
How do you prevent AI models from "hallucinating" or leaking private data?
We use retrieval-augmented architecture (RAG) and strict data governance rules. The AI is grounded strictly in your verified internal data, and access controls ensure users only see information they are authorized to view.
Will this process disrupt our current daily business operations?
No. We build data pipelines and infrastructure in parallel with your existing systems, ensuring zero downtime or disruption to your ongoing operational workflows.
get in touchHave a project in mind? Let's figure it out together.
Tell us what you’re building or trying to fix — let’s see how we can help.
Our Location
Singapore (HQ) — 33 Ubi Ave 3,
#05-26 VERTEX, Tower B,
Singapore 408868.
Other Offices
India, USA, France.